Dwi Yuda

DwiYuda

I audit my own work before someone else has to.

Informatics graduate from Universitas Islam Riau, Pekanbaru. I work on computer vision, LLM applications, and the evaluation that decides whether either one is telling the truth.

dwiiyudaaa@gmail.comCV (PDF)LinkedInGitHub

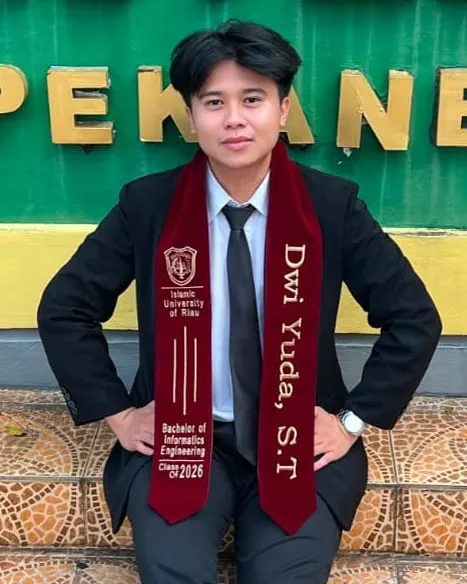
Dwi Yuda in a dark suit, wearing a maroon graduation stole
            reading Bachelor of Informatics Engineering, Class of 2026, in
            front of a Pekanbaru sign.
Pekanbaru, July 2026.

Where the habit came from

I was born in Batam and live in Pekanbaru. Between the two I spent junior and senior high school at a pesantren, an Islamic boarding school. Arabic came from those years, and I can still hold a conversation in it, though I would not claim more than that.

The language faded faster than the thing underneath it. What stayed was the practice of staying with one text until it gave way, which turns out to be most of what reading a paper or a stack trace asks of you.

Most of what I know as an engineer came from problems that were not mine. As a teaching assistant I reviewed six final-year projects across object detection, time series, clustering, and retrieval-augmented generation. The code and the reports belong to the people who wrote them. What I kept is range. The same category of mistake turns up in every one of those domains, and I have learned where it tends to sit.

When a task gets heavy my reflex is to build a tool for it instead of working faster. That is how the grading system began. A reminder service that mostly keeps quiet came from the same impulse. Both were things I wanted to stop doing by hand.

It is also how I ended up auditing my own thesis dataset and finding a leak in it. The audit turned out to prove me wrong, which was its own kind of useful. I would rather report a smaller number that holds than a larger one that does not, and I would rather find the hole myself than have someone find it during a defence.

2022 to 2026

  1. Enrolled in Informatics at Universitas Islam Riau

    What followed ran four years, without a repeated course.

  2. Vice chairman, HIMATIF

    Seven operational divisions and 50 members, reporting to the chair.

  3. Desa Binaan, Pulau Gadang

    Community programme in Kampar. Pre-survey ran on 25 October.

  4. Teaching assistant

    Six courses and nine classes over the four semesters that followed.

  5. Journal article published, village internship begins

    I-Com Vol. 5 No. 1 on 10 March. OpenSID deployment starts the same month.

  6. Thesis defended

    Passed outright, scored 82.07, graded A. Six credits, no revision round.

  7. Commencement

    The degree was finished in July. What is left is the ceremony.

Four I can defend line by line

Student ID card forgery detection

Final year project · PyTorch, FastAPI, Next.js 14, OpenCV ·Repository

Card checks at the university library were a person looking at a card, and the printed QR code was never wired to any database. This is a four-stage pipeline that decides instead, and shows its reasoning. It reaches 97.74% accuracy and a 0.9912 ROC-AUC at native resolution, and runs in 4 GB of VRAM.

  • 1,645 images
  • 5 forgery scenarios
  • 4 GB VRAM
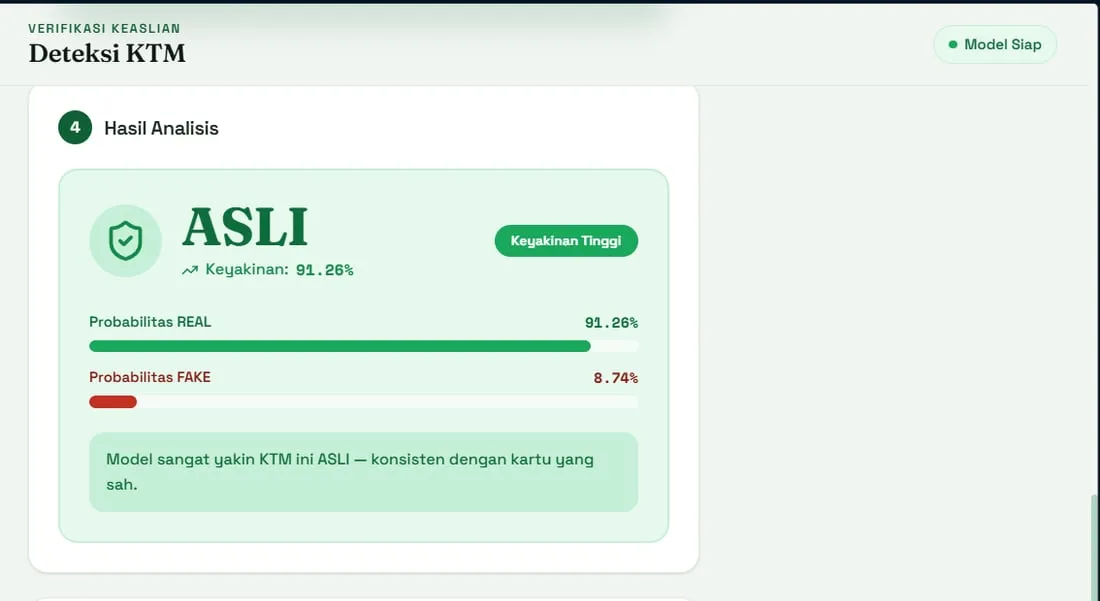
The detector's result panel reading ASLI, meaning genuine,
              with 91.26% confidence and a probability bar for each class.
Accepted. 91.26% confidence, above the gate.
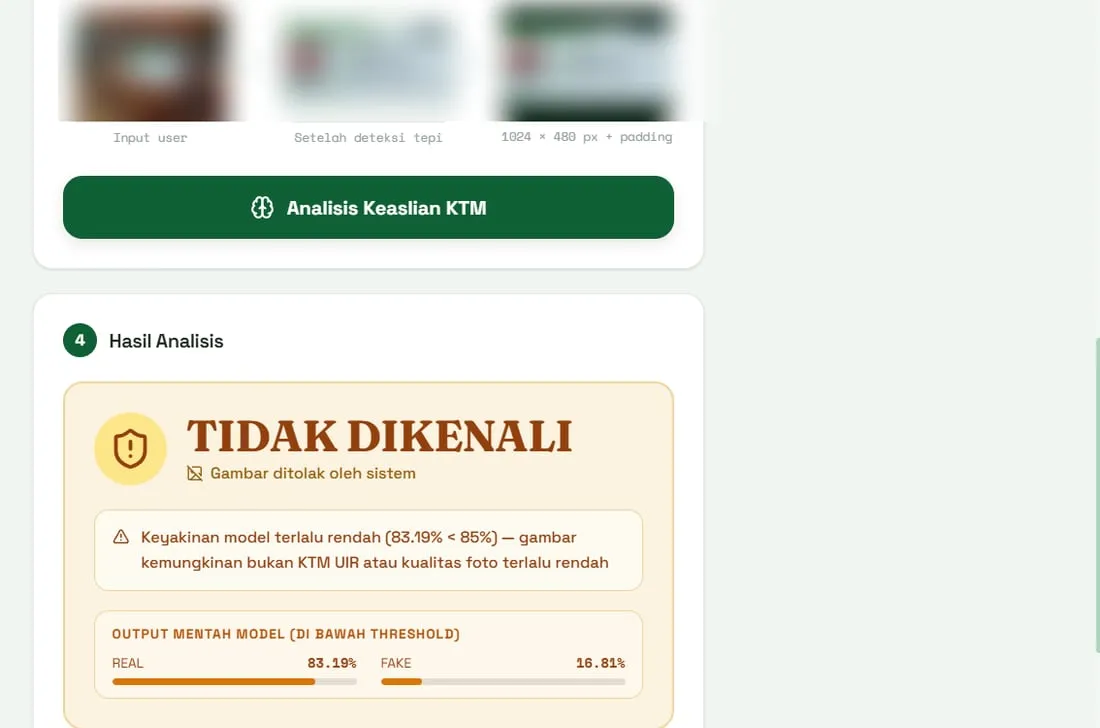
The same panel reading TIDAK DIKENALI, meaning unrecognised,
              because model confidence of 83.19% fell below the 85% threshold.
Refused at 83.19%, below the 85% gate. It declines rather than guesses.
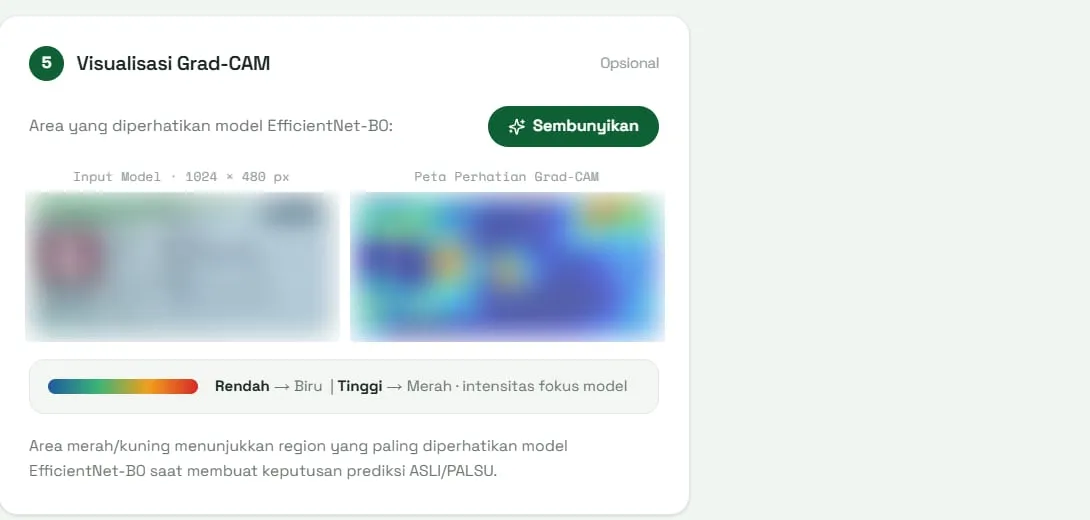
Grad-CAM view: the model input beside a heat map of the regions
            that drove the prediction, with a low-to-high colour legend.
Grad-CAM over the same card. Card details are blurred here because the card belongs to someone else; the heat pattern is the point.
How the pipeline works
  1. 01Qwen3-VLSemantic gate. Rejects anything that is not an ID card, zero-shot.

    It has to throw out a photo of a desk, a hand, a blank wall, before any of that reaches the classifier. Evaluated separately with an LLM-as-a-judge pass over card and non-card images, where it scored perfectly.

  2. 02Florence-2 + CannyPhrase grounding locates the card, then edge detection crops and deskews it.

    Florence-2 says where the card is, Canny finds its edges, and the crop straightens it. The classifier never sees the desk it was lying on, so background stops being a feature it can cheat with.

  3. 03EfficientNet-B0Binary classifier, genuine against forged.

    Two-phase transfer learning from ImageNet: the head trains first with the backbone frozen, then the whole network fine-tunes. Mixup at alpha 0.4, AdamW, seed 42. The shipped model runs at 1024×474 and fits in 4 GB of VRAM.

  4. 04Grad-CAMHeatmap over the region that drove the decision.

    This is the part that keeps the rest honest. On a font forgery the heat sits on the text block; on a face swap it sits on the portrait. If it had lit up the background instead, the accuracy figure would have meant nothing.

The audit

Four models scored a perfect 1.0000. I went looking for a data leak, found one that contaminated 29.1% of the test set, fixed it, and the accuracy did not move. The leak was real and it explained nothing.

Nine card families, two images each. R is the genuine scan, F the forgery built from it.
Train
R211F211R214R219F219F226R233F233F240R261F261
Val
R226R255F255
Test
F214R240R247F247

48 of 165 test images contaminated on the 80:10:10 split. That is 29.1%.0 of 165 contaminated. Every derivative of one card lands in the same subset.

Before the rebuild, images made from the same physical card were shuffled independently, so one card could appear in both the training set and the test set. Rebuilding the split by card family put every derivative of a card into a single subset, bringing contamination to zero.

Read what happened next

Every forgery was built from a real card and kept its number, so real_214 became fake_214. My split script shuffled the genuine files and the forged files independently, which let two halves of one physical card land on opposite sides of the train-test boundary. I rewrote the split to work on card families. Contamination went to zero.

Then I retrained, and it was still 1.0000.

A five-fold group-aware cross-validation agreed. At 1024×474 the two classes genuinely do separate, and the contamination had been riding along without changing the outcome. I had spent the audit proving my own suspicion wrong, and reported it that way.

My examiners raised a different objection. If every model scores 1.0, there is no basis for saying which one is better. They asked for results that were not perfect.

The quick way to do that is to make the numbers worse. I did not. Instead I ran a resolution ablation, holding every other parameter fixed and dropping the input to each architecture's native size, 224×224 for B0 and 300×300 for B3. Accuracy fell to between 0.9606 and 0.9774 on its own, and the fall carried information: the model leans on high-frequency forensic traces that do not survive being shrunk.

Every false negative in those runs came from one scenario. Font inconsistency. Not a single face swap, recapture, text patch, or hybrid got past. Four files defeated every native-resolution model I trained. Letterforms are the finest detail in the dataset, so they are the first thing to go when a card is squeezed to 224 pixels wide.
Automated practicum grading

Personal project, approved by the head of department · Python, Gemini 2.5 Flash

Marking practicum submissions by hand across eight sessions is slow and drifts between the first script and the fortieth. This reads the question, the answer key, and the lecturer's rubric, scores each submission against it, and writes an Excel recap with per-student feedback. Phase one passed after its marks were calibrated against manual grading.

  • 8 sessions
  • 3 Excel sheets per run
  • no RAG
Design decisions, and one that went wrong

No retrieval layer. The whole context fits in one prompt, so RAG would have been machinery with nothing to do. Every output carries a confidence label, and anything below high confidence goes to a human before it counts. Answer keys drafted by the model are validated by the lecturer before they grade anything. Student code is read, never executed.

The one that went wrong is worth more than the ones that went right. A quiz on SQL shipped to the model without its table schema, so the model guessed at column names, and students who had used the real ones were marked down for it. One went from 7 to 34.4 after the schema was added and the rubric was told to accept aliases. Another went from 44 to 46.4. A rubric on another session was also summing to 105%.

Both were caught by checking the machine's marks against marks given by hand, which is the only reason I trust the rest of them. The grader does earn its keep: it caught a foreign key pointing at the wrong table purely from reading, without running a line.

Each run writes one workbook with three sheets:

Rekap
NIM, name, status, total, confidence, needs review
Detail
NIM, name, criterion, score, feedback
Flag
NIM, name, status, reason for review

Only the column layout is shown. The real workbooks hold student names, email addresses, and marks, so none of it belongs here.

Hening, a reminder service that mostly stays quiet

Personal project · Cloudflare Workers, KV, OpenRouter, ntfy

Reminder apps fail because the content never changes: drink water at ten, at twelve, at two, whether or not you are in a meeting. Hening asks a model once an hour whether interrupting is worth it at all. Out of sixteen chances a day it says yes six to eight times. The silence is the feature.

  • 16 checks a day
  • 6–8 actually sent
  • <$1 a month
What the prompt has to get right

The hard part is not the code, it is telling the model that saying nothing is a valid answer and that the daily quota is not a target to hit. Three rules keep it from collapsing. A notification whose button was never pressed is logged as no response rather than ignored, because a busy person is not a refusal, and treating it as one makes the system go mute within days. Context older than ninety minutes is flagged as stale so it never tells someone they have been sitting for eight hours when their phone spent the night on a table. And the model returns structured JSON with a reason field, which is what makes calibration possible: you can read why it chose to stay quiet.

The README lists what it cannot do, and that list matters. The band is output only, since Huawei exposes no open API. What gets detected is the state of a phone, not the state of a person. Motorbikes are regularly classified as bicycles.

Cohort payment tracker

Built for my year group · Google Apps Script, Sheets

Nineteen of us owed each other money on a rotating schedule: every time one person defends, the other eighteen contribute. Tracking that in a chat thread does not survive contact with reality. This is a 19×19 matrix in Sheets with a small web form for updating from a phone, and a dashboard that recalculates itself because every column is a formula.

  • 19×19 matrix
  • 3 live charts
Why a spreadsheet and not an app

The people using it already lived in Sheets, and the whole thing had to be maintainable by someone who is not me after I graduate. Apps Script meant no hosting, no database, and no account for anyone to forget the password to. Duplicate entries are rejected at the form rather than cleaned up later, and the diagonal of the matrix is protected so nobody can pay themselves.

The repository stays private on purpose. The deployment URL is a write endpoint with no authentication, which is fine for a group of nineteen with the link and not fine in public.

Two jobs, both finished

  • Ran lab sections for six courses over four semesters, from Introduction to Programming through to Statistics and Probability.
  • Wrote the Statistics and Probability practicum myself and taught it: Z-test, T-test, ANOVA, confidence intervals.
  • Built the SQL lab modules on subqueries, views, and concurrency control. Student queries got debugged live, mid-session.
  • Reviewed six final-year projects across object detection, time series, clustering, and retrieval-augmented generation. Model setup, evaluation method, written report.
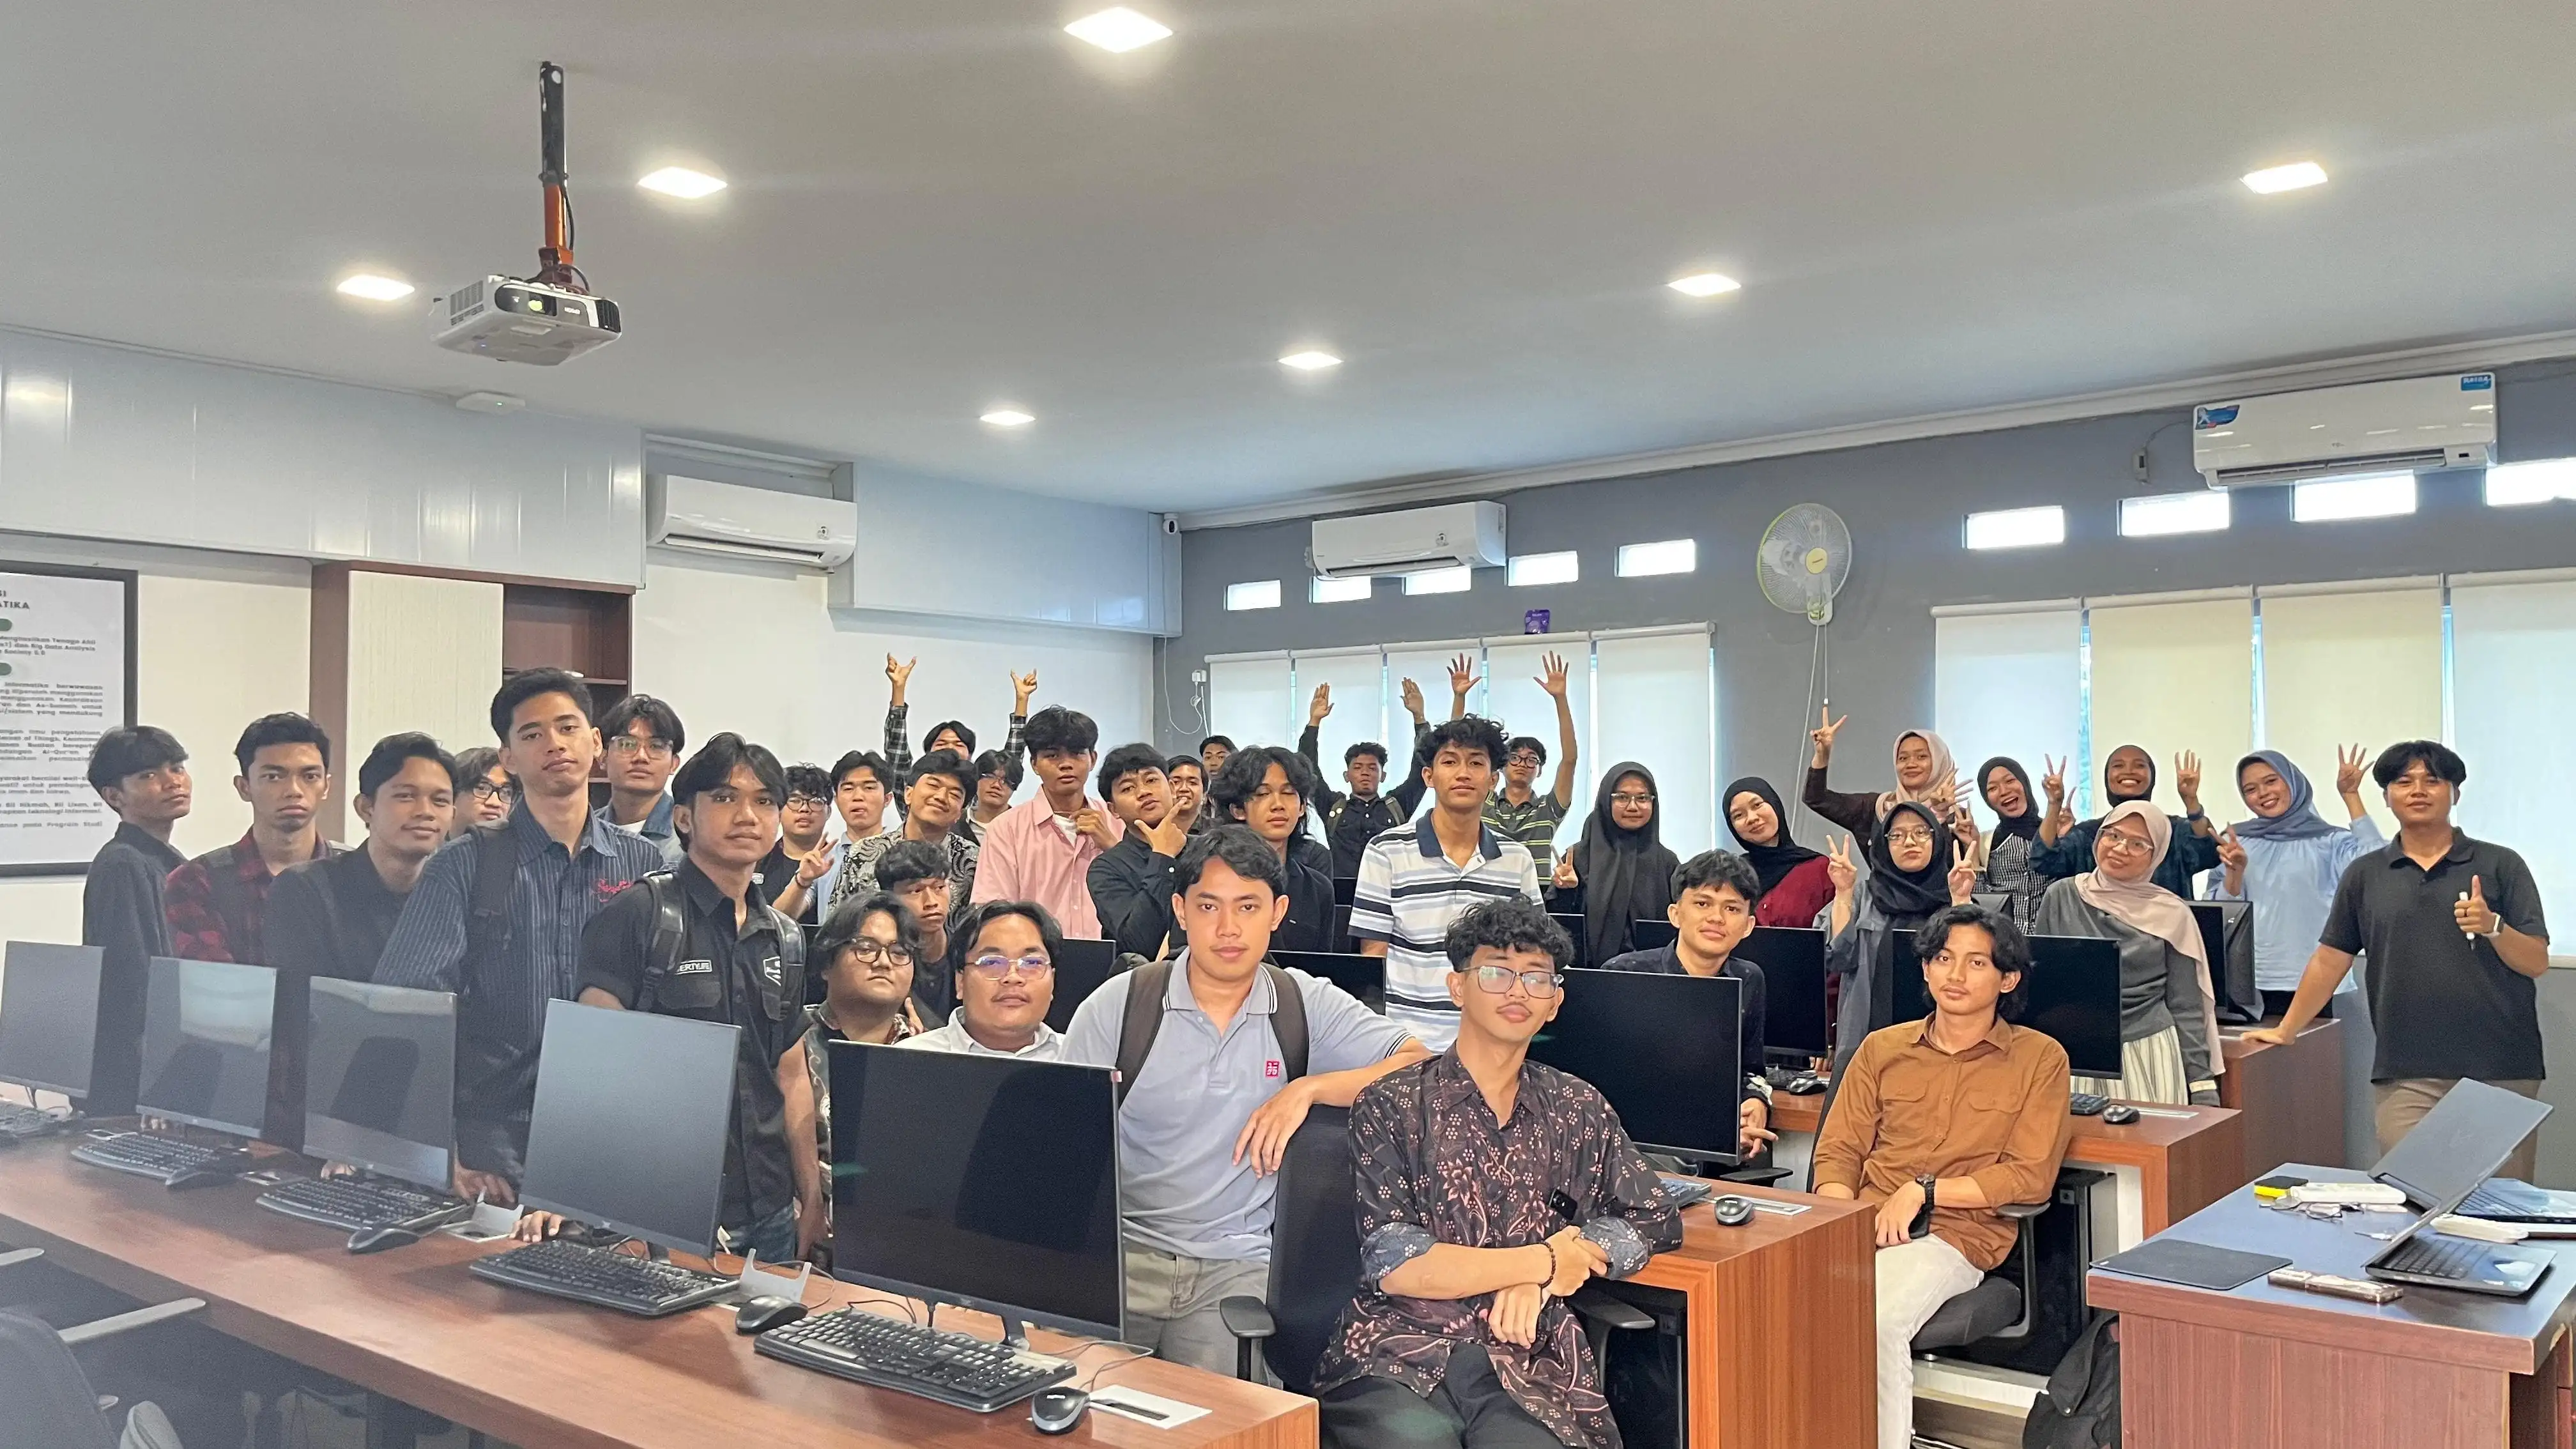
A computer lab at the end of a practicum session. Around
              thirty-five undergraduates stand and sit between two rows of
              monitors, facing the camera.
One of nine lab classes. Photograph used with permission.
  • Deployed OpenSID v22.10 on PHP, CodeIgniter, and MariaDB as the village's official information system.
  • Unlocked the User Group Management module, which OpenSID ships locked. Staff could then set their own access roles instead of sharing one administrator account.
  • Gathered requirements with village staff, then checked every figure with the finance officer before writing code.
  • Kept 77 MSME listings and the boundary maps current, on a scheduled backup.
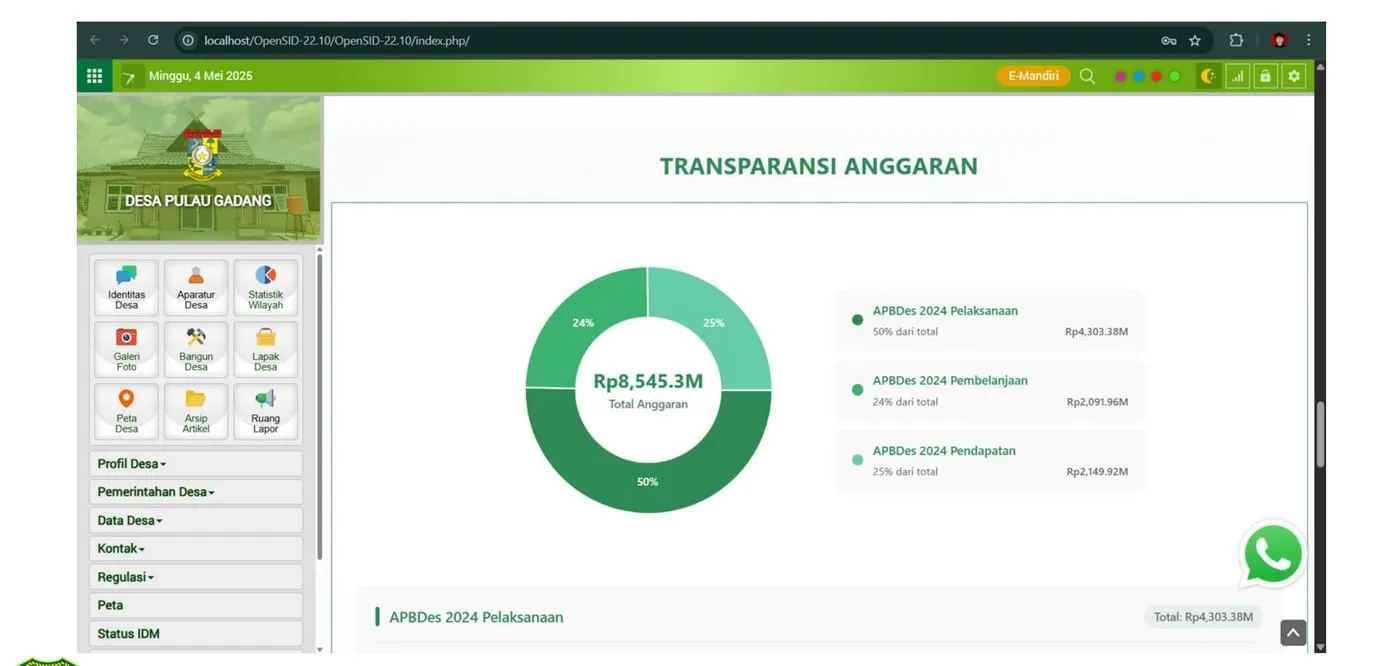
The same page after the rebuild: a single donut chart
            showing total budget with three labelled segments and their amounts
            listed beside it.
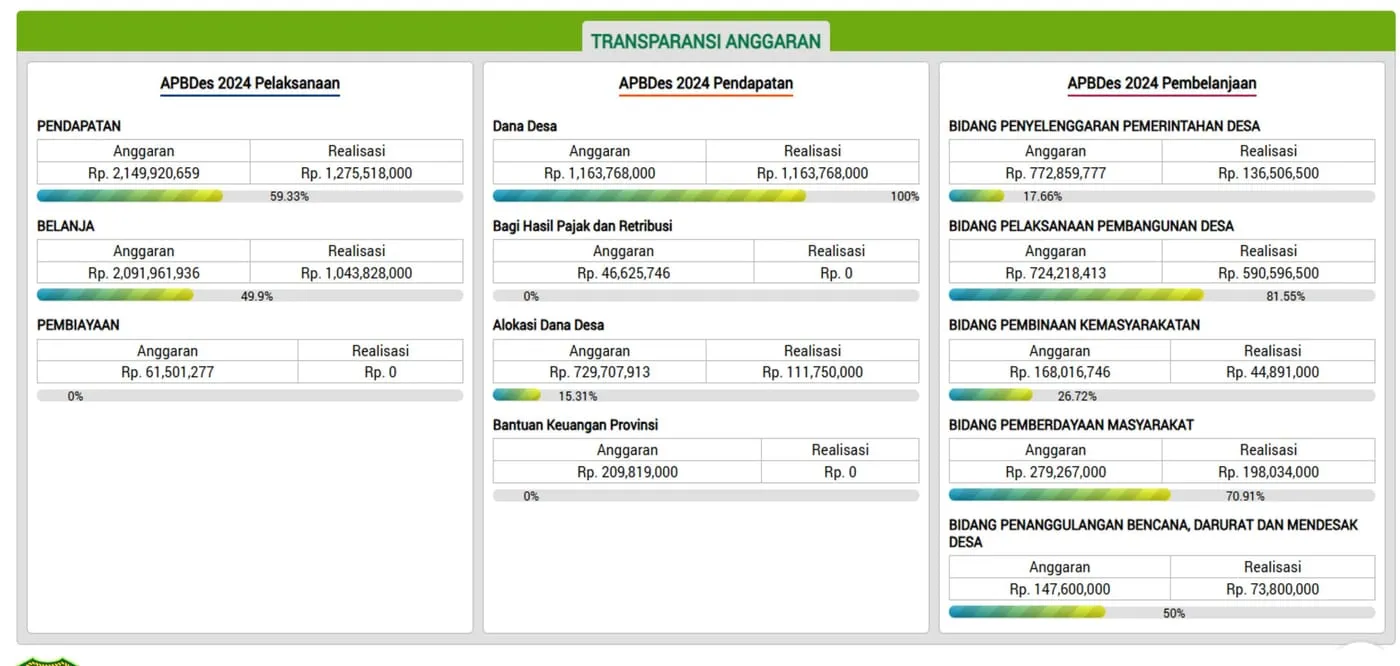
The village budget page before the rebuild: three columns
            of plain tables listing budget and realisation figures for revenue,
            spending, and financing.
BeforeAfter
Drag the handle. Three tables of raw figures on the left, one donut chart of budget against realisation on the right. The village head asked for proportion at a glance.
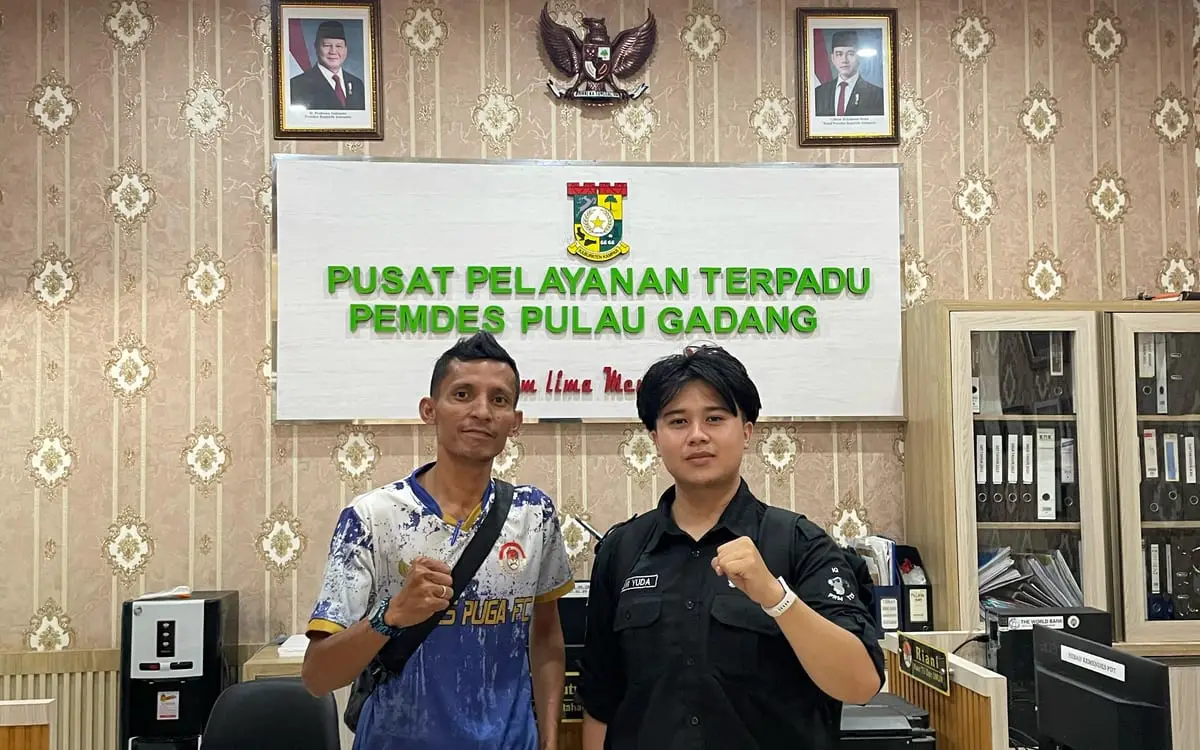
Standing with a member of village staff in the Pulau Gadang
                integrated service office, under the office's name board.
Checking figures at the village office before writing any code.
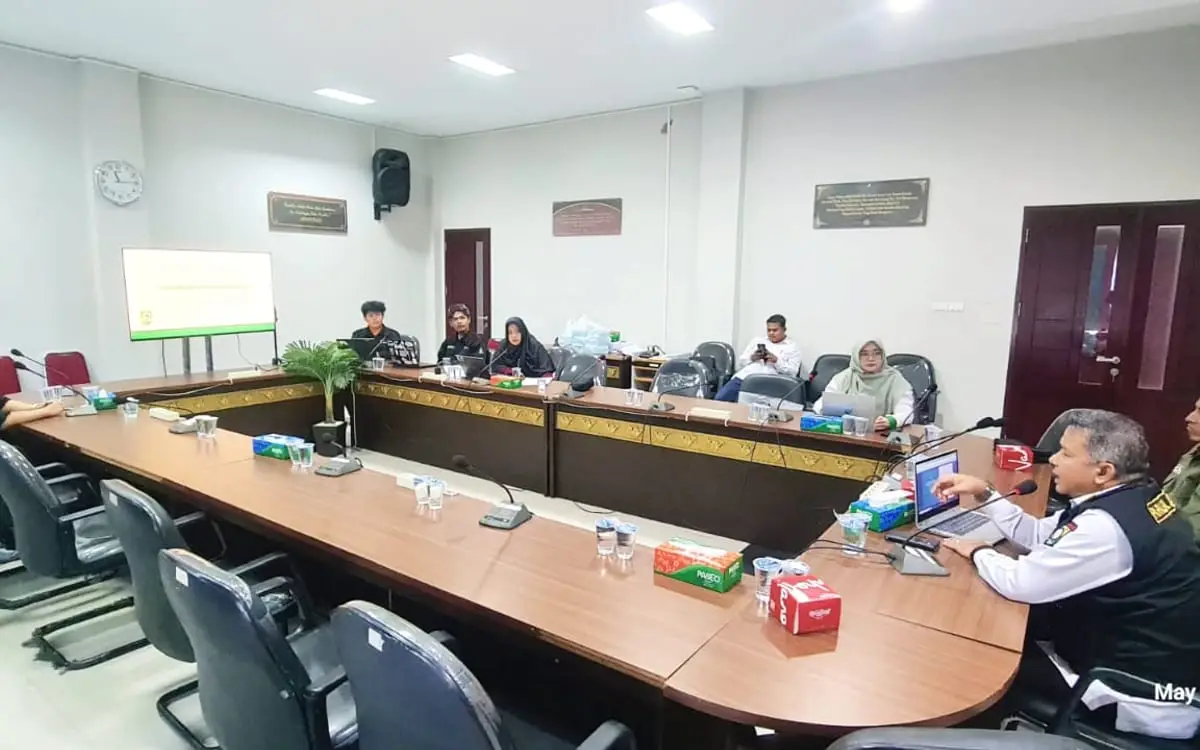
Presenting the rebuilt village website in the village meeting
                room, with the site projected on screen.
Presenting the result to village staff, 28 May 2025.

Running things I did not build

Vice Chairman, HIMATIF

Informatics Student Association, UIR · Feb 2024 – Apr 2025

7
Operational divisions supervised, with 50 members under them, reporting to the chair.
280
Participants at the student induction camp, coordinated against a committee of 100.
50
Vocational students at an IT and cyber security seminar at SMK Labor, delivered with twelve volunteers.

That heading is literal. The association's Next.js profile site was built by the Research and Technology division, not by me. I set the scope and reviewed what came back. The code is theirs, which is why everything here says directed rather than built.

Student team member, Desa Binaan

Pulau Gadang, Kampar · Oct 2024 – Mar 2025

A community empowerment programme run by a UIR student team. The pre-survey went out on 25 October 2024, and the sessions that followed were held at the village hall with the village head and every member of staff, on village law and on publishing budget records.

The programme was written up afterwards and published. It is the article in the next section.

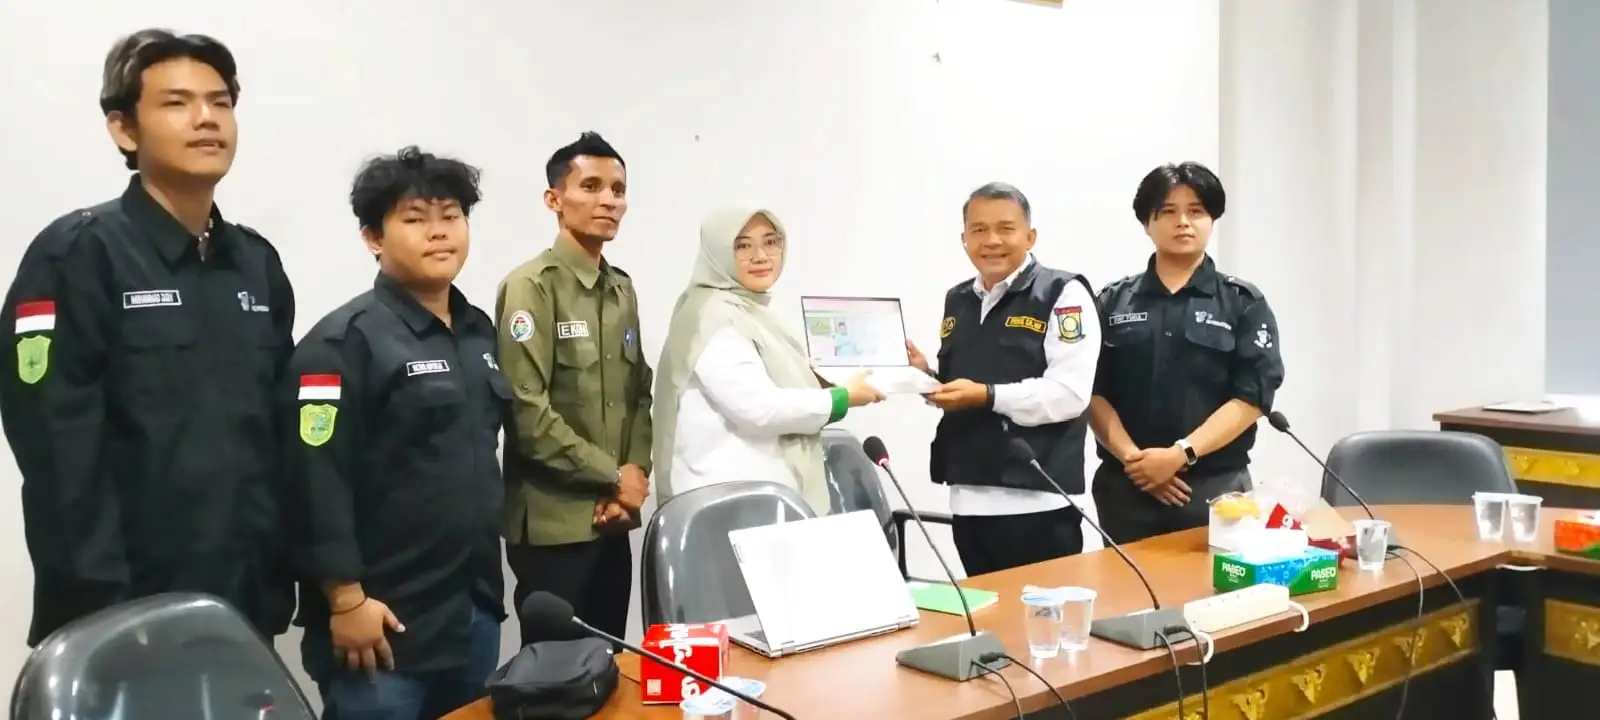
Handover in the village meeting room. A student team member
            passes a laptop showing the new site to the village head, with four
            others standing alongside.
Handing the finished site to the village head. Photograph used with permission.

One article, and what it is not

Susanti, H., et al. (2025). Pemberdayaan Desa Binaan Berbasis Budaya Hukum dengan Penerapan (SIMDES) Sistem Informasi Transparansi Dana Desa di Pulau Gadang. I-Com: Indonesian Community Journal, 5(1), 333–342. https://doi.org/10.70609/icom.v5i1.6599

The team was led by Dr. Heni Susanti from the law faculty, and the article reports the village programme rather than a study of my own.

I-Com is a national community-service journal. It is not Scopus-indexed and it is not a research venue. Read it as external evidence that the village work happened, and nothing more than that.

Certifications, and who issued them

  1. CCNA: Introduction to Networks

    Cisco Networking Academy · August 2024

This is the Networking Academy course credential, at student level. It is not the professional CCNA certification, and the badge above says so in its own words.

Four years, September 2022 to July 2026, with no repeated course.

What I use, and where I used it

Modelling

PyTorch
Both training phases of the detection model
Hugging Face Transformers
Qwen3-VL and Florence-2 in the pipeline
Scikit-learn
Metrics and StratifiedGroupKFold on the thesis data
OpenCV
Canny edge detection and deskewing before classification
Grad-CAM
Checking which region drove each decision

Evaluation

Group-aware splitting
Rebuilt the thesis split by card family
ROC-AUC, confusion matrix
Reported per model and per split
Ablation study
Resolution ablation that broke the 1.0 ceiling
Robustness benchmark
JPEG, blur, occlusion, rotation, noise
LLM-as-a-judge
Independent check on the semantic gate

Building

Python
The detection pipeline and the grading system
FastAPI
Serving the detection model
Next.js 14, JavaScript
The detection frontend
PHP, CodeIgniter, MariaDB
OpenSID at Pulau Gadang
SQL, MySQL
Lab modules I wrote for the database course
Git
Everything above

Languages

Indonesian
Native
English
Professional working
Arabic
Elementary, conversational

The through line

Most of this page is a record of checking things.

A dataset that turned out to be contaminated. An answer key that marked correct answers wrong. A website I directed but did not write, and said so on the page rather than hoping nobody asked.

Not one of those checks made a number larger. What they did was leave me with numbers I can still stand behind when someone asks how they were produced. That is the habit I would want you to take from here, more than any single result above it.

Built with Astro. It sets no cookies and runs no analytics. Every figure on this page traces back to a document, and the source is on GitHub.